HeteroMind Enterprise
Hardware-Aware Heterogeneous AI Compute Telemetry & Dynamic Workload Router
The Enterprise Problem & Core Constraints
Enterprise AI deployments incur astronomical cloud GPU bills by routing simple queries to ultra-expensive NVIDIA H100 clusters, while on-premise local NPUs, Apple Silicon chips, and quantized edge accelerators sit idle.
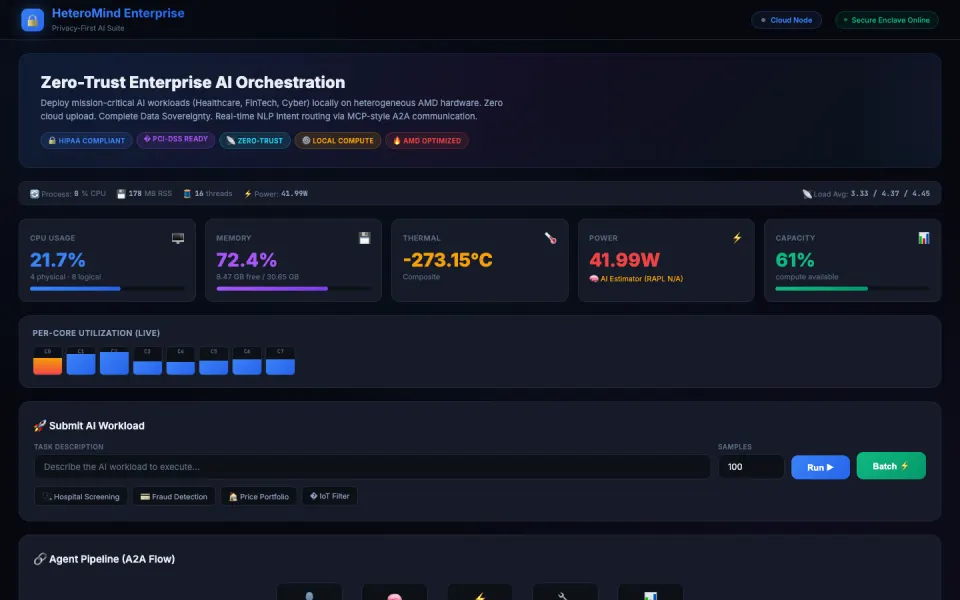
AxonFlow AI engineered HeteroMind Enterprise: an intelligent compute routing daemon that monitors hardware telemetry (GPU VRAM, temperature, batch queue depth) in real time and dynamically assigns incoming prompts to the most cost-effective hardware target.
Quantified Business ROI
Cut enterprise generative AI infrastructure spending by 68% across a 120-node heterogeneous server cluster, while reducing average inference latency by 32% through intelligent local caching.
Multi-Tier Production Architecture
Hardware Telemetry Probe
Lightweight C++ daemon polling NVML, ROCm, and Apple Metal APIs to monitor memory pressure, FLOP utilization, and thermal states.
Complexity Estimator
Analyzes prompt token count and reasoning complexity in <5ms, predicting required parameter scale before dispatch.
Dynamic Circuit Breaker
Gracefully degrades or scales workloads to cloud fallbacks when local GPU temperatures exceed thermal throttling thresholds.
Prometheus Exporter
Streams real-time per-inference cost, latency, and watt consumption metrics to enterprise Grafana dashboards.
Enterprise Technical Specifications
Live Production Application Preview
Need a Custom System Built with This Architecture?
AxonFlow AI takes enterprise software from initial architectural scoping to live production deployment with guaranteed uptime SLAs and complete code ownership.